
Sorting Algorithms
In short: sorting means repeatedly comparing neighbours and fixing
anything out of order. Bubble sort does that directly — walk the list,
swap any adjacent pair that's backwards, and keep walking it again from the
start until every pair is in order. Insertion sort builds up a sorted section one item at a time,
sliding each new item back until it's in place. Both are easy to picture
and both are slow on large lists — Python's own sorted() and .sort()
use a much faster algorithm, so real code almost never hand-rolls either.
What real code does reach for is key= (what to compare by) and
reverse= (which direction), plus the one guarantee that makes multi-field
sorting possible: Python's sort is stable — items that compare equal
keep their original relative order. The DSA course covers merge sort, quick
sort and their real complexity; this is the Python-shaped version: how to
actually sort things correctly.
Line up delivery parcels by weight, one swap at a time
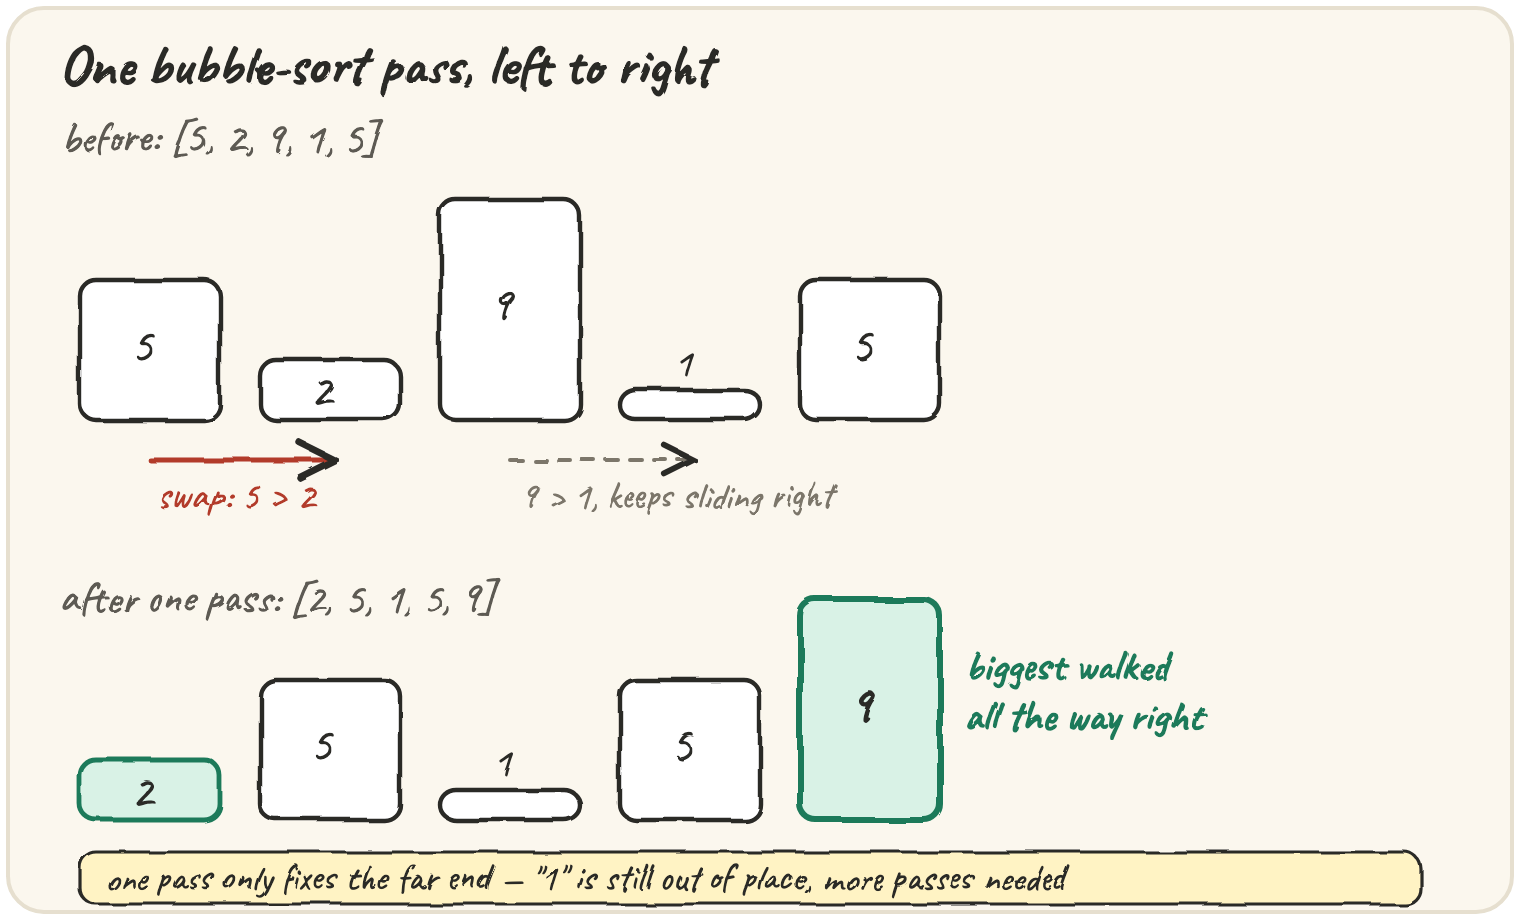
A sorting conveyor only ever compares two parcels sitting next to each other, swapping them if the heavier one is in front. One full pass pushes the single heaviest parcel all the way to the back — but nothing else is guaranteed sorted yet:
The mistake people make reading this for the first time is assuming the
inner loop alone sorts the list. It doesn't — the drawing above shows
exactly one pass of that inner loop: 9 reaches the end, but 1 is still
stuck in the middle. It takes the outer loop running several more passes
before every value has bubbled into place. Insertion sort reaches the
same result from the other direction — instead of bubbling the biggest
value out, it grows a sorted prefix at the front, one value at a time:
Both algorithms do real, useful work — and both do more comparisons than they need to as a list grows, which is exactly why Python doesn't use either one internally.
Sort race results by finish time
sorted() and .sort() take a key function, called once per item, and a
reverse flag. key=lambda r: r["time"] is just a one-line unnamed
function — the Functional Python section covers lambda properly; here
it's only ever used this one way, as a "sort by this field" pointer:
sorted() always returns a new list and leaves the original alone.
.sort() is the opposite: it sorts the list in place and returns
None — on purpose, as a signal that nothing new was created. The mistake
almost everyone makes once, exactly once, is assigning that None back
over the list they meant to keep:
TypeErrorRun it and read the error. Then print the fastest time correctly.
list.sort() on its own line sorts times and leaves it exactly where it
is; times = sorted(times) makes a new sorted list and names it times.
Either works — writing times = times.sort() combines them into the one
combination that doesn't.
Rank a leaderboard with tied scores
Real rankings often need a tie-break: same score, different names, decided alphabetically. The direct way is a tuple key — compare by score first, name second, in one call:
-p["score"] sorts highest score first while p["name"] still sorts
alphabetically ascending for the tie — negating only the field that needs
flipping. The mistake is reaching for reverse=True on the whole tuple key
instead, assuming it only reverses the "main" field:
players = [
    {"name": "Zoya", "score": 80},
    {"name": "Ambika", "score": 80},
    {"name": "Om", "score": 95},
]
ranked = sorted(players, key=lambda p: (p["score"], p["name"]), reverse=True)
print([p["name"] for p in ranked])A tuple key doesn't actually need Python's sort to be stable — it already compares both fields itself. Stability matters in a different, common pattern: sorting in two separate passes, tie-break field first, main field last:
The second sort only ever moves players relative to score — it never has
to decide between two players with the same score, so the alphabetical
order the first pass left behind survives untouched inside every tie.
That's the real payoff of stability: sort the less important key first, the
more important key last, and ties resolve themselves without a tuple at
all.
Quick practice
nums = [4, 1, 3]
result = sorted(nums)
print(nums, result)words = ["pear", "fig", "apple"]
words.sort(key=len)
print(words[0])pairs = [(2, "b"), (1, "z"), (1, "a")]
print(sorted(pairs))🎯 Your turn
Write leaderboard(players). Each player is a dict with "name" and
"score". Return the names sorted by score, highest first; break ties
alphabetically by name:
leaderboard([{"name": "Om", "score": 95}, {"name": "Zoya", "score": 80}])→["Om", "Zoya"]leaderboard([{"name": "Zoya", "score": 80}, {"name": "Ambika", "score": 80}])→["Ambika", "Zoya"]
Hint — sorted(players, key=lambda p: (-p["score"], p["name"])), then
pull out "name" from each entry.
Press ▶ Run, try the Live App chips, then ✓ Check. After that, the practice set below writes bubble and insertion sort by hand, and proves to itself that Python's own sort is stable.