
A CSV analyzer reads rows and columns from a delimited text file and computes useful summaries.
Parse quoted fields, convert values to useful types and build filtering and aggregation steps around the data’s structure.
A report is only as interpretable as the rows that feed it. Follow a small comma-delimited file from raw text through typed records to statistics, keeping rejected line numbers alongside accepted data. Then inspect where a delimiter split stops being sufficient for actual CSV.
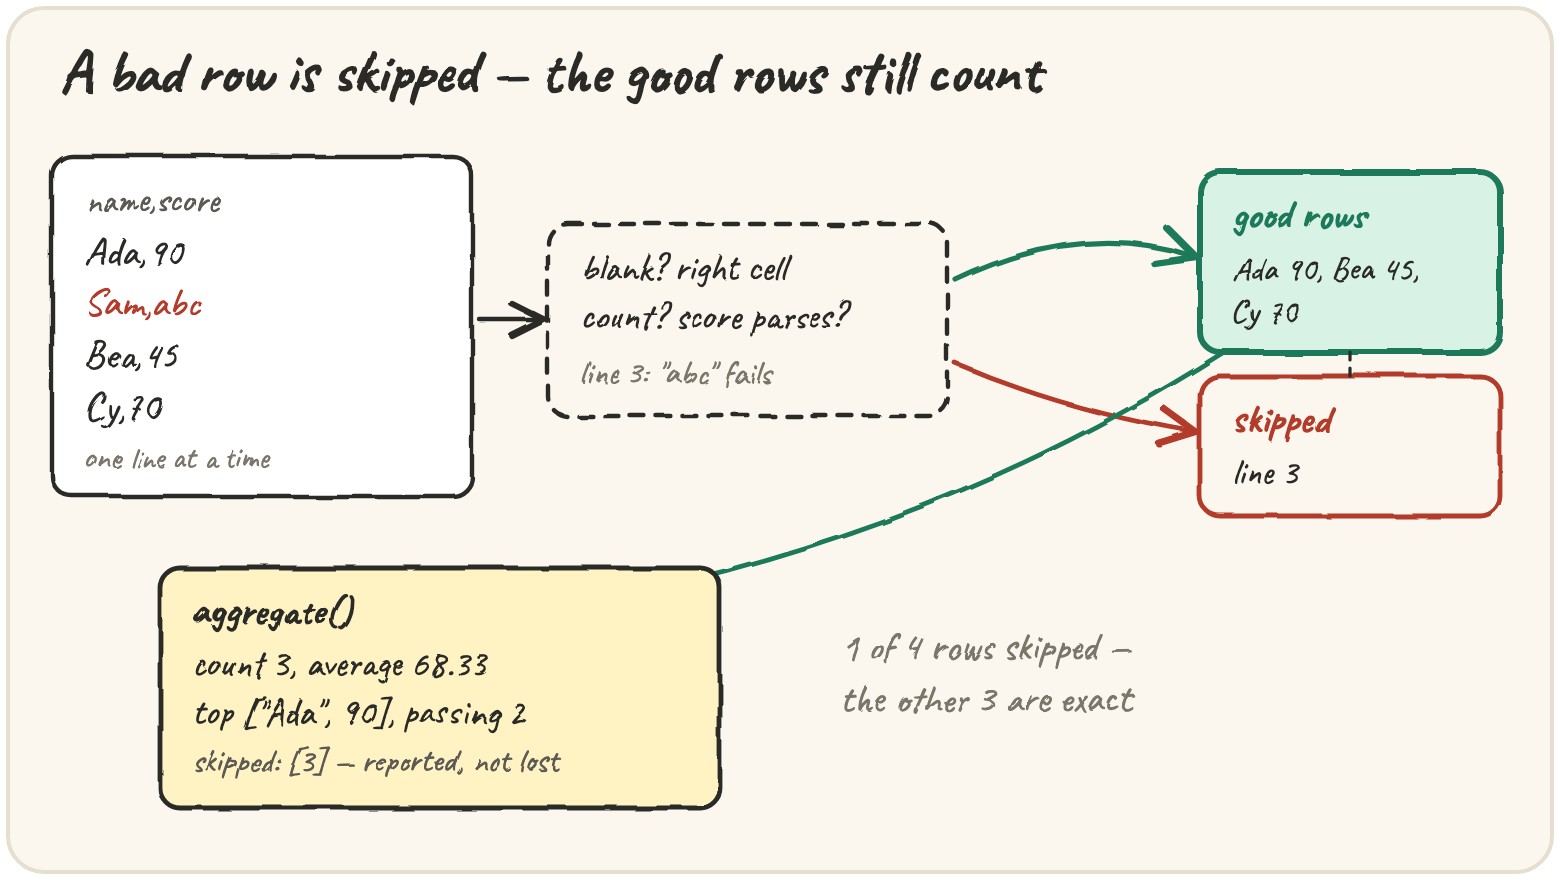
A teacher exports her class's marks from a spreadsheet. This sample contains one record per line with commas between cells. She wants four numbers at a glance: how many students, the class average, the top scorer, and how many passed.
That sounds like five lines of code, and for a perfect file it is. Less tidy exports can differ: columns arrive in a different order, cells carry stray spaces, someone typed abc
into a score, a row lost its comma. This project builds an analyzer for a restricted comma-delimited format:
one record per line, no quoted commas or embedded newlines. It computes a
summary from accepted rows and reports which lines were rejected. A real
CSV parser is introduced below so this simplification is explicit.
The finished analyze(text) turns this:
name,score
Ada,90
Sam,abc
Bea,45
Cy,70
into {"count": 3, "average": 68.33, "top": ["Ada", 90], "passing": 2, "skipped": [3]} —
line 3 skipped, not the whole file refused.
Every box is live — edit and ▶ Run.
The plan
Data work is a pipeline: each stage takes the previous stage's output and hands a cleaner version on. Keeping the stages apart gives you intermediate values to inspect when a result is wrong:
The practice cards combine string splitting,
exceptions and small functions — parse_rows,
column, filter_rows, aggregate. The Your task editor assembles them into
report(lines) for tidy input. The project at the bottom handles the messy file.
The analyzer never opens a file. It takes the file's text as a string, so every
test can hand it a file written inline. A file-reading adapter can use with open(path, encoding="utf-8", newline="")
and pass the text onward; the parsing rules must still match the file format.
Preparing this topic’s interactive investigation…
Milestone 1 — from text to typed rows
A CSV line is a string. split(",") cuts it into cells, still strings; a score is only
useful once it's a number:
name.strip() removes the stray spaces. The score gets no .strip(), yet it still
works:
print(int(" 75 ") + 1)The first thing a real file does to this function is hand it the header row:
ValueErrorRun it and read which value int() refused. Then skip the header so only data lines are added.
text.splitlines() splits on \n, \r\n or \r — whichever the spreadsheet used —
and doesn't invent an empty last line when the file ends with a newline.
Where the simplified parser stops
The record "Rao, Asha",90 contains two CSV cells, but split(",") sees
three pieces. Quotes change the meaning of commas; a quoted field can even
contain a newline. Use the standard library to handle those syntax rules:
The CSV reader solves structure: which characters belong to each cell.
It normally still returns strings. Your code must decide which columns are
required, whether a score is an integer, and whether that integer is allowed.
Parsing -500 successfully does not make it a meaningful mark.
Keep the supplied project on its stated simple format so its physical-line
numbers stay unambiguous. For full CSV, one record may span several physical
lines; reader.line_num reports lines read, not a record counter. Decide
which identifier an error report should show before extending the parser.
Milestone 2 — columns and filters
With rows as lists, "select a column" and "keep rows where…" are one comprehension each — the same two questions every data tool asks:
>= keeps a student who scored exactly the pass mark — the boundary is where graders
disagree, so decide it on purpose.
Milestone 3 — the summary
aggregate rolls a list of numbers into one dict of statistics. An empty class has no
average, so the guard comes first:
The top scorer needs the whole row, not just the number, so max gets a key saying
what to compare:
rows = [["Ada", 90], ["Bo", 90], ["Cy", 70]]
print(max(rows, key=lambda r: r[1])[0])That tie rule is worth writing down in your report's documentation: "first in file order wins" is a decision, not an accident.
Milestone 4 — reading a messy file
Now the real file. Two ideas carry it.
Find columns by name, not position. A header of score,name puts the score first.
header.index("score") finds it wherever it is, and extra columns like id or house
are simply never looked up.
Skip a bad row; don't abandon the file. One abc in 200 rows shouldn't lose 199
good ones. Wrap the fragile step in try/except ValueError, record the line number,
and move on. Step through it:
enumerate(lines[1:], start=2) numbers the data lines as a person counts them in an
editor, header as line 1. A skipped list of [3] means "open the file, go to line
3" — that is what makes the report actionable.
Files arrive in lots of shapes, and each check needs its place in the loop:
Blank line?
if not line.strip(): continue. A trailing empty line isn't an error — skip it without reporting it.
One more thing a real file can do: arrive without the columns you need. That isn't a
bad row — nothing can be salvaged — so the analyzer returns
{"error": "missing column: score"} instead of guessing.
A file object reads the same way, line by line. io.StringIO wraps a string so it
behaves like an open file; swap it for open(path) and nothing else changes:
Note the \n still attached to each line — line.strip() or splitlines() removes it.
Count what survived and what was lost
The report's denominator is accepted rows, not all input lines. In the opening
example, count = 3 and the average is (90 + 45 + 70) / 3; counting the bad
score as zero would lower the average without evidence that anyone scored zero.
Ignoring it without reporting the skip would hide missing information.
There are three distinct failure levels: a missing required header prevents
interpreting any row; a malformed row can be rejected independently; a valid
but implausible score needs a domain rule. Duplicate header names are another
ambiguity: header.index selects the first. A stronger importer should reject
or explicitly resolve duplicates instead of silently pretending the schema
is unambiguous.
The stages also give a debugging order. Inspect parsed cells, then typed rows, then the statistic. A wrong average may originate in a wrong column selection rather than in division.
Extend the importer to report a reason with each rejected row and reject
scores outside 0..100. Design a file with a quoted name, a reordered header,
a score of zero, one malformed score and no accepted rows. State which cases
need the real CSV reader and how the summary should expose data loss.
Build the analyzer
Write analyze(text, pass_mark=60). text is a whole CSV file; line 1 is the header.
- Find the
nameandscorecolumns by header name (trim and ignore case); other columns are ignored. If either is missing, return{"error": "missing column: score"}(naming the first missing one, checkingnamefirst). - Blank lines are ignored. A line with the wrong number of cells, or a score that isn't a whole number, is skipped: record its line number (header = line 1).
- Return
{"count", "average" (2 dp, 0 if none), "top" ([name, score], first on a tie, None if none), "passing" (score >= pass_mark), "skipped"}.
- a clean file
- columns in any order
- header and cells trimmed
- extra columns ignored
- bad rows by line number, blanks ignored
- skipped rows don't count
- exactly the pass mark passes
- custom pass mark
- ties go to the first
- header only
- missing column
- empty file
When it passes, ask what your analyzer would say about a file that is all bad rows.
Is count: 0 with a long skipped list the answer you'd want as the teacher?
🎯 Your turn
Build the four practice cards, then write report(lines) in the editor beside the
lesson for tidy "name,score" lines (no header):
report(["Ada,90", "Sam,60", "Bea,45"])→{"count": 3, "average": 65.0, "top": ["Ada", 90], "passing": 2}report([])→{"count": 0, "average": 0, "top": None, "passing": 0}
Press ▶ Run, try the scenario chips, and hit ✓ Check. ✅
Practice — level up
0/4 solvedSolve each in its own editor — Run to try, Check to grade. Stuck? Reveal a Hint, or the full Solution + walkthrough.
Each line is "name,score". Write parse_rows(lines) returning [[name, score], ...] with the name trimmed of spaces and the score converted to an int, so later maths works.
Rows are lists like ["Ada", 90]. Write column(rows, index) returning the list of values at position index from every row — the 'select one column' of any data tool.
Write filter_rows(rows, index, minimum) keeping only the rows whose value at index is >= minimum, in their original order. A row exactly at the minimum is kept.
Write aggregate(nums) returning {"count", "sum", "avg", "min", "max"} with avg rounded to 2 decimals. For an empty list return count, sum and avg as 0 and min, max as None — never divide by zero.