
A string is Python’s text type: an ordered sequence of Unicode characters.
Clean, slice, split and format text while tracking the boundaries and new strings each operation produces.
A form gives you characters; your program must decide which to preserve, remove, extract or display. Starting with simple text and indices, we will clean a name, select a suffix and split fields. Watch where a transformation loses information: a tidy-looking result is not automatically valid data.
Clean a name from a form
A sign-up form hands you whatever the person typed: " aSHA rao ".
Before you save it, trim the spaces and fix the capitals:
Step through the chain and watch each step make a new string while raw
stays as it was:
Methods chain left to right: .strip() returns a string, and .title()
runs on that. The same kit cleans an email, and in asks "is this text
inside that text?":
Notice the line email = email.strip().lower(). Leave out email = and
nothing happens:
name = "  asha rao "
name.strip()
print(f"[{name}]")This should print [Asha Rao]. It prints the raw input. Make the cleaning stick.
Choose the boundaries. Follow the selected positions.
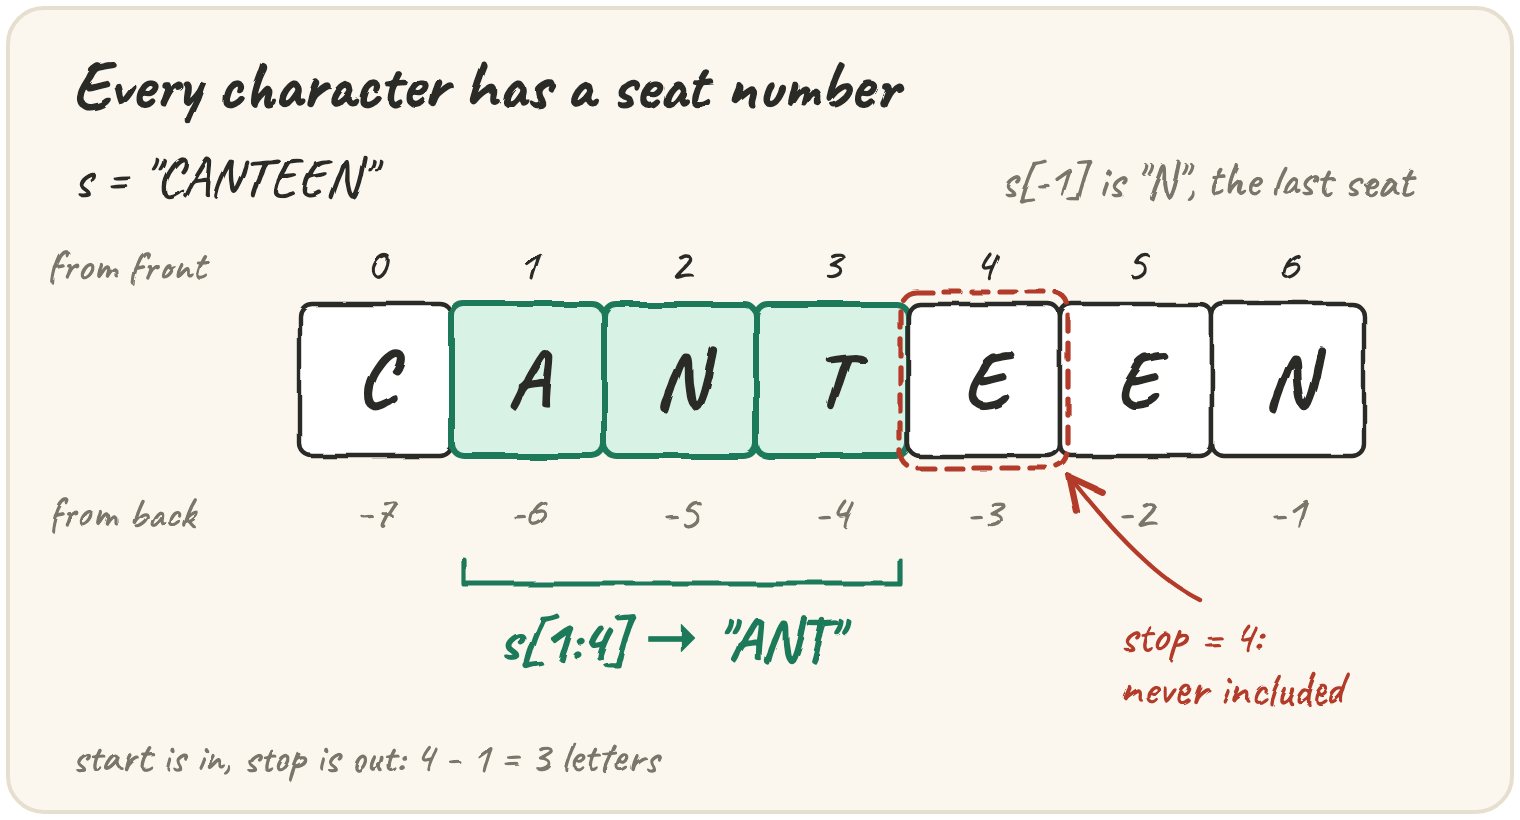
A slice visits positions toward its stop boundary. The stop position is excluded; reversing the step changes the direction.
s[1:4]→"ANT"
Interactive model of Python slicing over Unicode code points. A visible character may contain several code points. Blank bounds are omitted, which differs from explicitly using -1 with a negative step.
Preparing this topic’s interactive investigation…
Slices select between boundaries
For text = "PYTHON", six characters occupy indices 0 through 5.
text[1:4] takes indices 1, 2, 3: its stop boundary is excluded.
There are 4 - 1 = 3 characters. Think of cuts before and after characters,
rather than two characters to include.
text[99] asks for one nonexistent item and raises IndexError. A slice
can be empty or stop at the end, so it does not raise for these bounds.
Negative indices count from the end: -1 is the last character.
text[-4:] therefore returns the whole string when it has fewer than four
characters; masking requires a separate length policy.
Mask a card number
A payment screen shows only the last four digits of a card:
XXXXXXXXXXXX4444. The digits sit at positions 0 to 15, so the last four
are at 12 to 15. First try:
card = "4111222233334444"
print(card[12:15])Counting from the front is fragile anyway, because not every card has 16
digits. Count from the back instead. card[-4:] means "from the fourth-last
to the end", whatever the length. And * repeats a string, + glues two:
Step through the masking one line at a time:
The first idea most people have is to overwrite the front of the string:
TypeErrorRun it and read the error. Then make it print the masked card.
Replacing the whole variable is fine. Reaching inside the characters is what Python refuses.
Split a dinner bill
Four friends type their names into a bill-splitting app as one line:
"Asha,Ravi,Meena,Kabir". .split(",") cuts at every comma and gives you a
list. .join() does the reverse, and the string you call it on is the
glue that goes between the pieces:
After the colon inside { } comes a format spec: .2f means two decimal
places, <8 and >9 set a width for tidy receipt columns. The f-string
always makes new text; share itself is still the number 310.0.
Two things go wrong here all the time. If someone types spaces after the
commas, .split(",") keeps them: "Asha, Ravi".split(",") gives
['Asha', ' Ravi'], with a sneaky space inside the second name. And people
write .join() backwards:
AttributeErrorRun it: lists have no join. Put the glue in front.
One-liners and traps
Trap:
"Total: " + 250is aTypeError. Python will not glue text to a number. Writef"Total: {250}"or"Total: " + str(250).
Choose what information cleaning may remove
"a,,b".split(",") produces ["a", "", "b"]: the blank middle field is
information. " a b ".split() produces ["a", "b"]: whitespace runs and
edge blanks are deliberately discarded. Use the first behavior for a simple
delimited record, the second for command words. Real CSV also needs quote
handling; its parser is covered in the CSV project.
Cleaning is not always harmless. .strip() removes whitespace at the ends,
not inside; .lower() changes case but does not validate an identifier.
Keep the original if its spelling matters. A string is a sequence of Unicode
code points, so an accented character plus a combining mark or an emoji
sequence can occupy several indices despite looking like one symbol.
The ASCII examples here avoid that extra display problem.
Build a parser for " item-17 : ready " that splits only at the first colon,
trims both fields and preserves their internal characters. Decide what to
report for "item-17:" and "item-17" before writing it. An empty value and
a missing separator should remain distinguishable.
Quick practice
print("o'brien".title())print(len("a b c".split()))code = "PNR4521789"
print(code[3:] + code[:3])TypeErrorA booking screen crashes on this line. Make it print the message.
🎯 Your turn
Write receipt_header(restaurant, table), the tidy line at the top of every
receipt:
receipt_header("cafe python", 12)→"Cafe Python — Table 12"receipt_header("THE GRILL", 8)→"The Grill — Table 8"
Hint: clean the name with restaurant.strip().title(), then build the
line with an f-string: f"{...} — Table {table}". That dash is an em dash, —.
Press ▶ Run, try the Live App chips, then ✓ Check. Green means this piece of the app is built.