
Prefix Sums, Difference Arrays & Windows
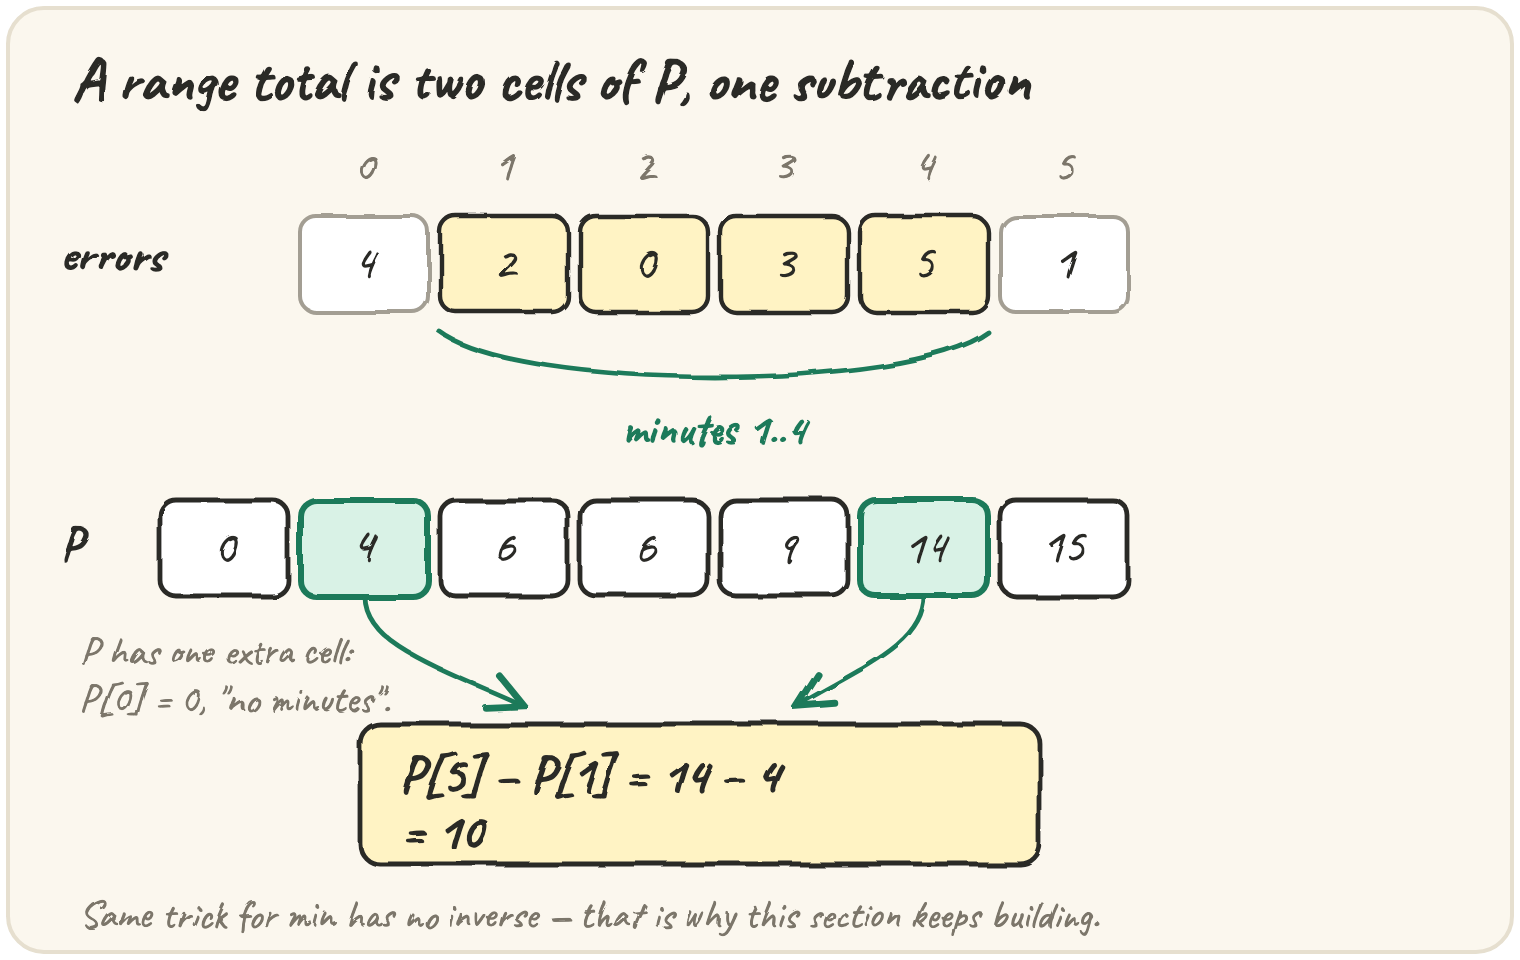
In short: build a running-total row once, P[i + 1] = P[i] + a[i], and any
range total becomes one subtraction, P[r + 1] − P[l]. The spare P[0] = 0
cell means a range starting at minute 0 needs no special case. The same trick
runs backwards: a difference array turns a wide range update into two
point writes, with one final sweep — itself a prefix sum — turning differences
back into values. Both only work because addition can be undone; min has no
inverse, which is why the rest of this section exists.
From this section on you build Quarry, a search-and-storage engine: the kind of program that sits under a dashboard, keeps a log of everything that happened, and answers questions about it fast. Later sections give it an index, a text search and a storage layer. This section gives it an analytics engine.
The raw material is simple. Quarry keeps one number per minute: how many requests arrived, how many errors, how many bytes were written. A day is 1,440 minutes, a month is 43,200, and the dashboard asks the same shape of question over and over:
How many errors between minute
land minuter?
Every lesson in this section answers that question under a harder rule. Here the log never changes after it is written. Next lesson it gets edited. By the end it takes range updates, minimum queries and lives on disk.
The brute force, and what it costs
The obvious answer is a slice and a sum:
Each query reads every minute it covers. One query over a month is 43,200 reads; a dashboard with twenty panels refreshing every few seconds asks thousands of them. That's O(n) per query and O(n·q) in total, and nearly all of it is re-adding numbers that were added a moment ago by the previous query.
The prefix row
Add everything up once, left to right, and keep every running total:
P[0] = 0 and P[i + 1] = P[i] + errors[i].
P[i] is the total of the first i minutes. It has one more cell than the log,
and P[0] = 0 stands for "no minutes at all". That spare zero is what makes the
next line work without special cases:
total of minutes l..r = P[r + 1] − P[l].
P[r + 1] counts everything up to and including minute r. P[l] counts
everything before minute l. Subtracting removes exactly the part you don't
want. Watch the row fill, then watch two queries each read just two cells:
Building the prefix row costs one pass. After that, any range total is two cells and one subtraction, however wide the range.
P[0] = 0 is the total of no minutes. The label under each cell is the minute it adds. 7 cells. At index 0. 1 of 7 cells settled.
Preparation is O(n) time and O(n) extra memory. Every query after that is
O(1). For q queries the total drops from O(n·q) to O(n + q).
errors = [3, 1, 4, 1, 5]
P = [0]
for e in errors:
    P.append(P[-1] + e)
print(P)The off-by-one is the whole difficulty. Try the formula on the smallest range there is:
P = [0, 3, 4, 8, 9, 14]
l, r = 2, 2
print(P[r + 1] - P[l], P[r] - P[l])Now the same thing as code you can edit. Change errors, or the query, and run
it again: the drawing is your code's own run.
Your prefix row, built one cell at a time, then one query answered with two reads.
Here is a teammate's version. It passes on some queries and fails on others:
Minutes 1..4 hold 2 + 0 + 3 + 5 = 10, but this prints 5. The subtraction stops one minute early.
❓ Cross-question — "Why not store
Pwithout the leading zero?" You can, but then every query starting at minute 0 needs anif l == 0branch, and every reader of your code has to check that branch. The spare cell costs one integer and removes a special case. That trade shows up again and again in this section.
Why subtraction is allowed
The prefix row works because addition can be undone. P[r + 1] is too much by
exactly P[l], and subtraction removes it. Any operation with an inverse gets the
same trick: products (divide, if no zeros), XOR (XOR undoes itself), counts.
min has no inverse. Knowing the smallest error count in minutes 0..9 and in
0..3 tells you nothing about minutes 4..9: the minimum might sit in the
part you're trying to remove. That single fact is why the rest of this section
exists. Blocks, Fenwick trees and segment trees are all ways of answering range
questions when you can't subtract, or when the log keeps changing.
Difference arrays: the mirror image
Sometimes the questions are cheap and the updates are expensive. A backfill job says "add 5 to every minute from 1 to 3", then "add 2 to minutes 2 to 5", a thousand times, and only at the end does anyone read the result. Doing each update cell by cell is O(width) apiece.
A difference array stores how each minute differs from the one before it.
Adding d to minutes l..r changes only two differences: minute l goes up by
d relative to its neighbour, and minute r + 1 comes back down by d. So an
update is two writes, and one prefix pass at the end rebuilds every value:
A range update touches two cells of the difference array. One running-sum sweep at the end turns differences back into values.
Add 5 to minutes 1..3. Minute 1 starts 5 higher than minute 0. 7 cells. At index 1.
The sweep is a prefix sum. Prefix sums and difference arrays undo each other, the way integration and differentiation do. Step through the rebuild yourself:
Windows
Section 1's sliding window answered "which 3 back-to-back minutes were busiest?"
by adding the minute that enters and subtracting the one that leaves. The prefix
row answers it too: the window starting at i of width k totals
P[i + k] − P[i].
Both are O(n). They differ in what they're good for. The slide uses O(1) memory and visits windows in order, so it suits a live stream. The prefix row costs O(n) memory but answers any window, in any order, as many times as you like. So it suits a dashboard. Section 1's growing-and-shrinking window, meanwhile, needs every count to be non-negative. The prefix row doesn't care about signs, which is what makes this lesson's boss exercise possible.
How many queries before building the row pays off? For a 1,000-minute log, an average rescan reads about half the log, so q queries cost about q·1000/2 cells, while the prefix row costs 1000 + q:
| queries q | rescanning | prefix row | prefix row is cheaper by |
|---|---|---|---|
| 1 | 500 | 1,001 | 0.5× (it's dearer) |
| 10 | 5,000 | 1,010 | 5× |
| 100 | 50,000 | 1,100 | 45× |
| 250 | 125,000 | 1,250 | 100× |
| 1,000 | 500,000 | 2,000 | 250× |
Below a few hundred queries the one-off pass over the log is a large share of the prefix row's cost. Above that the rescans pull away. A dashboard reaches 250 queries in seconds.
Coming from Java/JS:
itertools.accumulate(errors, initial=0)builds the prefix row in one call, like areducethat keeps every intermediate value. The loop is spelled out here so you can see each cell arrive.
Idioms & real-world patterns
Counting ranges with a hash map
"How many ranges of minutes have a net change of exactly t?" A range l..r hits
t when P[r + 1] − P[l] = t, so P[l] = P[r + 1] − t. Walk the row once and
keep a dict of how many times each prefix total has been seen. Each new prefix
looks up its partner in O(1):
That's O(n) for a question that looks as if it needs O(n²) pairs, and negatives don't break it.
⚡ Advanced — two dimensions
A heat map of errors per server per minute is a grid. The prefix idea extends:
S[i][j] totals the rectangle above and left of cell (i, j), and any rectangle
is four reads with inclusion–exclusion. That's the capstone exercise.
Quick practice
P = [0, 2, 5, 5, 9]
l, r = 1, 3
print(P[r + 1] - P[l])Adding 5 to minutes 1..3 should leave minute 4 back at 0, but it prints [0, 5, 5, 5, 5] — the bump never ends.
🎯 Your turn
Build Quarry's first piece: range_totals(counts, queries). counts is the
per-minute log and each query is [l, r] with both ends included. Return one
total per query, in order. Build the prefix row once, and answer every query with
one subtraction.
range_totals([4, 2, 0, 3, 5, 1], [[1, 4], [0, 0], [0, 5]])→[10, 4, 15]
Then press ▶ Run, tap the Live App try chips to call it with different inputs, and hit ✓ Check. Green means this piece of Quarry is built. ✅